Unsupervised learning finds structure in data without supplied target labels. An algorithm might group similar examples into clusters or learn a compact representation from which it can reconstruct an input. Its training objective measures the structure it is trying to capture.
For example, a collection of photographs may have no captions or category names. An unsupervised method can group photographs by their visual features, leaving a person to inspect what the groups have in common. Those groups can guide further exploration or help organize a dataset for supervised learning.
Contents
The features learned by deep neural networks can be used for the purposes of classification, clustering and regression.
Neural networks can learn features through different training objectives. An autoencoder learns to reconstruct its input from an internal representation. A supervised classifier learns features that help predict supplied labels. Backpropagation can adjust the network’s weights for either objective.
The features learned by neural networks can be fed into any variety of other algorithms, including traditional machine-learning algorithms that group input, softmax/logistic regression that classifies it, or simple regression that predicts a value.
So you can think of neural networks as feature-producers that plug modularly into other functions. For example, you could make a convolutional neural network learn image features on ImageNet with supervised training, and then you could take the activations/features learned by that neural network and feed it into a second algorithm that would learn to group images.
Here is a list of use cases for features generated by neural networks:
Visualization
t-distributed stochastic neighbor embedding (T-SNE) is an algorithm used to reduce high-dimensional data into two or three dimensions, which can then be represented in a scatterplot. T-SNE is used for finding latent trends in data. For more information and downloads, see this page on T-SNE.
K-Means Clustering
K-means groups vectors into a chosen number of clusters, k. Each cluster has a center called a centroid. The algorithm assigns each point to its nearest centroid, then moves each centroid to the mean of its assigned points. It repeats these steps until the assignments or centers stabilize.
The objective is to minimize the sum of squared distances between points and their assigned centroids. For the one-dimensional data [1, 2, 9, 10], two clusters centered at 1.5 and 9.5 have a total squared distance of 0.25 + 0.25 + 0.25 + 0.25 = 1. This objective is also called inertia. Different initial centers can lead to different solutions.
The resulting cluster IDs identify groups discovered in the data. They carry no supplied meaning such as “cat” or “dog”; interpreting a cluster takes inspection. That makes k-means unsupervised even though it has an optimization objective. See the scikit-learn guide to k-means.
Transfer Learning
The features used in clustering can also serve other learning tasks. Transfer learning reuses a model trained on one task or dataset for another. For example, you can take the activations of a ConvNet trained on ImageNet and use them as features for a nearest-neighbor classifier. That classifier learns from labeled examples, so this next step is supervised.
K-Nearest Neighbors
K-nearest neighbors predicts from the labeled examples closest to a new input. For classification, neighbors vote on a category; for regression, their target values can be averaged. A kd-tree is one way to accelerate that search by partitioning the space along its coordinate axes. Other implementations search distances directly or use different tree structures.
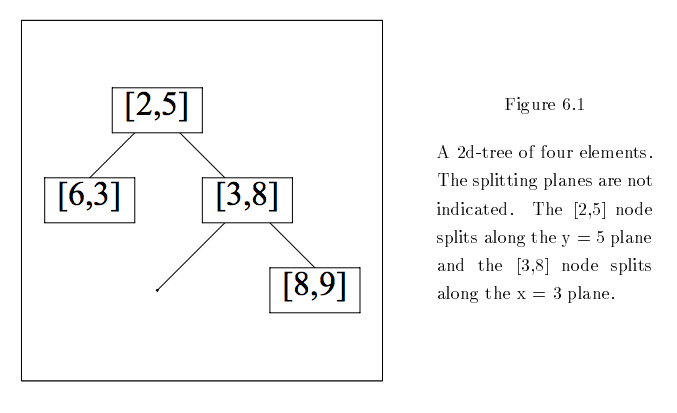
Let your input and training examples be vectors. Training vectors might be arranged in a binary tree like so:
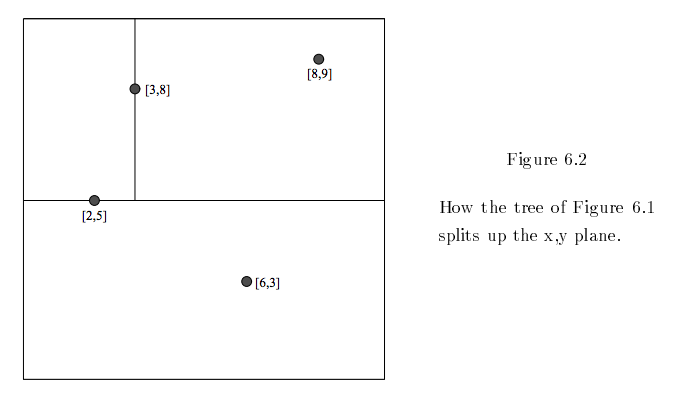
If you were to visualize those nodes in two dimensions, partitioning space at each branch, then the kd-tree would look like this:
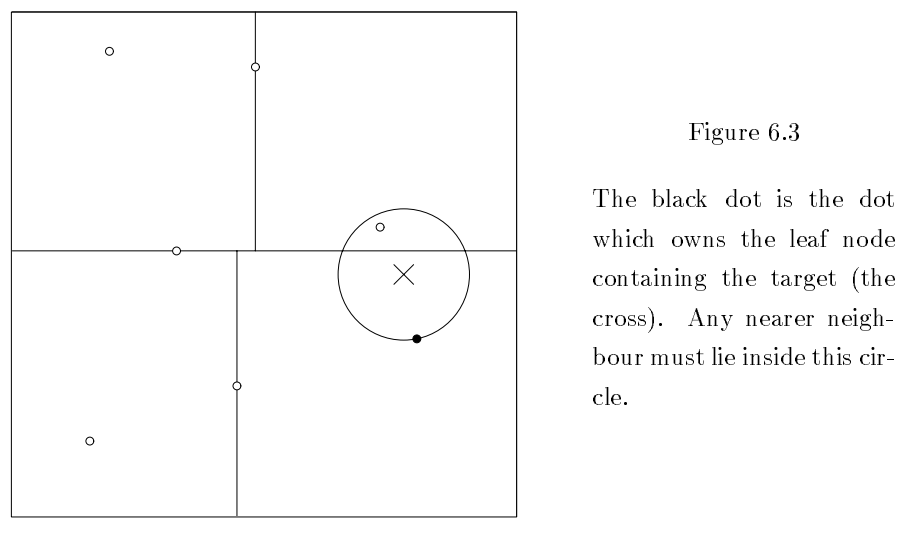
Now place a new input, X, in the tree’s partitioned space. Once the search finds a candidate neighbor, draw a circle centered on X with a radius equal to that candidate’s distance. A closer neighbor must lie inside the circle. The search can skip regions entirely outside it and check overlapping regions for a better candidate.
And finally, if you want to make art with kd-trees, you could do a lot worse than this:
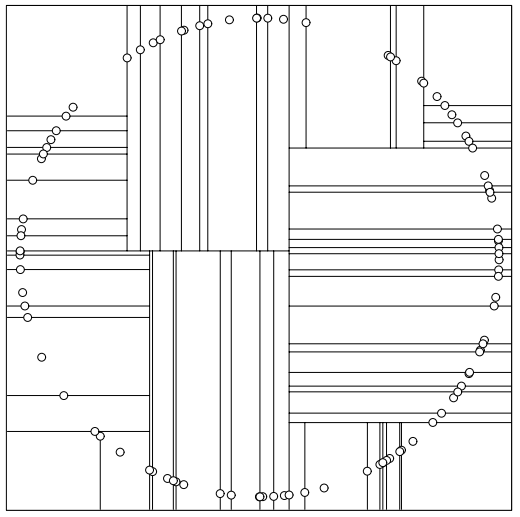
(Hat tip to Andrew Moore of CMU for his excellent diagrams.)
Other methods
In natural language processing, using words to predict their contexts, with algorithms like word2vec, is a form of unsupervised learning.